Start a Project

Lider Digital Archive

Document AI

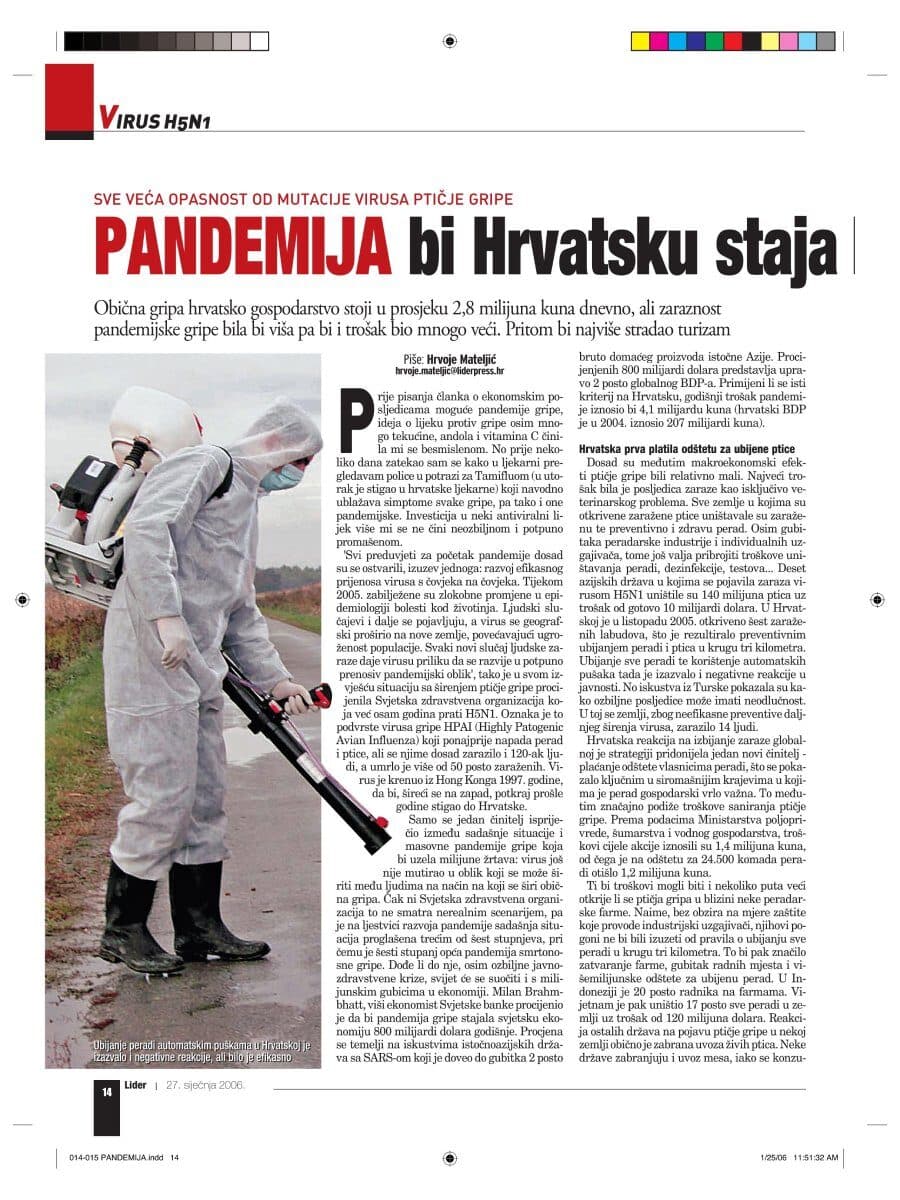
Original Lider magazine page showing complex multi-column layout with images and Croatian text - demonstrating the complexity of documents processed

Decades of business journalism, locked in PDFs. We built an AI pipeline that extracted, structured, and indexed 50,000+ articles – making them searchable and ready for the age of AI.

Articles Processed
50K+
of Archive Content
Decades
Language Processing
Croatian
Searchable Data
Structured

Not Your Typical OCR Job

Magazine layouts break standard document processing – multi-column text, images that split articles, stories that span pages.

Layout Detection & OCR

Magazine pages aren't documents. Articles wrap around images, jump across pages, and share space with ads. Standard OCR gives you garbled soup.

  • Multi-column text recognition
  • Article boundary detection
  • Image and caption identification
  • Multi-page article tracking

Croatian Language AI

Most AI models struggle with Croatian. Diacritical marks get mangled, context is lost, and business terminology comes out wrong.

  • Custom language model training
  • Diacritical mark preservation
  • Context-aware text correction
  • Author and title extraction

Processing Pipeline

Four stages from raw PDF to structured, searchable content.

  1. PDF Ingestion

    Automated processing of scanned magazine pages with quality normalization

  2. Layout Analysis

    Computer vision for structure detection, segmentation, and reading order

  3. OCR & Extraction

    Text recognition with Croatian language processing and error correction

  4. Data Structuring

    Converting to searchable, structured format with metadata enrichment

What We Built

Custom algorithms for the specific challenges of magazine digitization.

Multi-Page Tracking

Articles that continue on page 47 get automatically connected. Our algorithms track continuity markers and content flow across the entire magazine.

Author Recognition

Pattern recognition extracts and normalizes author information from various byline formats and positions within magazine layouts.

Auto-categorization

Machine learning classifies articles by topic, industry, and content type – making the archive instantly navigable by subject.

Post-Processing Pipeline

Every extracted article runs through validation and quality control. Spell checking, format normalization, metadata enrichment, and deduplication happen automatically.

  • Automated quality scoring
  • Cross-reference validation
  • Human review queuing for edge cases

Full-text Indexing

Every word, every article, instantly searchable. The archive becomes a queryable database, ready for AI applications.

Results & Impact

From locked PDFs to living, searchable archive.

Digital Preservation

Decades of Croatian business journalism preserved in structured, future-proof format. Full-text search across the entire archive.

  • Complete archive digitization
  • Rich metadata for every article
  • Full-text search capability

AI-Ready Data

The structured archive now powers Pitaj Lider – the AI assistant. What was locked in PDFs is now training data for business intelligence.

  • Powers AI assistants
  • Semantic search ready
  • RAG-compatible format

Have Archives to Digitize?

Our document AI handles complex layouts, multiple languages, and archives of any size. Let's talk about your digitization project.

Open for new projects

See starting prices for this kind of work, or tell us what you're building and we'll reply within 24 hours. Rather use one of our products, like Tvrtko.ai, Moj Kolega or Titlomat? Those are open too.